Motion analysis · 1226 frames · 50 fps

Paquita in
Coefficients

A 24-second classical variation, extracted from video, fitted to a cosine series, and reduced to 38,808 numbers. Everything below is drawn live from those numbers — nothing here is a recording.

Rawas the model saw it
Fittedcosine series
The skeleton is reconstructed every frame by evaluating the series below. Drag coefficients kept toward 2 to watch the choreography dissolve into its lowest harmonics — the dance becoming a smear of its own average. The left figure is the unfitted output: every frame estimated independently, no smoothing, every tremor left in. Watch a held position and the raw limbs shiver while the fitted ones hold still.

The representation

One formula per joint

Each of the 66 channels — 33 joints, two coordinates each — is a truncated cosine series. The basis is defined for real t, not just integer frames, so the same coefficients deliver both smoothing and resampling at any framerate. There is no separate interpolation step.

x(t) = Σk=0..K−1 ck · wk · cos( πk(2t+1) / 2N )
w₀ = √(1/N), wk = √(2/N), N = 1226 frames

A cosine basis rather than a Fourier one, because a dance is not periodic: she does not finish where she began. A Fourier series would impose a seam between the last frame and the first, and truncating across that artificial discontinuity produces Gibbs ringing in the limbs. The cosine transform mirrors the signal instead of wrapping it, so the endpoints match by construction.

80,916
raw numbers
38,808
coefficients shipped
334 KB
the whole variation
100%
frames tracked

Finding one

The variation occupies five dimensions

Poses were centred on the hip midpoint and scaled by torso length, so what remains is shape rather than stage position. Principal components over that 66-dimensional space collapse hard: three components carry 85% of the variance, five carry 90%, eleven carry 99%.

Cumulative variance. The elbow at five is unusually sharp.

Scrubbing those three sliders moves along the axes the choreography actually uses, rather than along time. The grey figure is the mean pose; brass is the current position in eigen-space.

Finding two

A 2:1 rhythm, and what it means

Because the motion is now a function, it can be differentiated term by term — exact joint velocities, with none of the noise amplification that finite differences inflict on pose data. The spectrum of that velocity, taken over the clean first 18.5 seconds, has a sharp fundamental and a stronger second harmonic.

Velocity spectrum. Fundamental 1.135 Hz (0.88 s cycle); second harmonic 2.270 Hz (0.44 s step).

That exact doubling is the signature of a left–right symmetric travelling step. Speed is a magnitude, so it peaks once per step, while a full movement cycle contains two steps — one on each leg. Symmetric gait always shows its strongest energy at twice the cycle frequency.

Finding three — a failed prediction

The held positions are not there

The source clip is titled a balance sequence, so the prediction was that velocity minima would locate the held balances automatically — choreographic structure falling out of the calculus. It did not work.

Shape velocity across the variation. Shaded brass: the three intervals that met the threshold. Shaded red: the turn sequence, where tracking degrades.

Two errors, compounded. The first was measuring absolute joint speed, which conflates the body changing shape with the dancer travelling and the camera moving — a balance held while travelling reads as fast. Refitting in normalised pose space corrected that and changed almost nothing, which is the useful part: it ruled out the measurement and left only the premise.

The premise was wrong. A balancé is a travelling rocking step, not a held stillness. Median shape speed is 0.925 torso-lengths per second — she is moving continuously, as that step requires. The regular oscillation visible above was never noise around held poses; it was the step rhythm, which is precisely what the 2:1 spectrum measures. Only three intervals qualify as held: the opening pose, a 2.3-second final position, and a fragment.

Finding four

One cutoff cannot serve a whole variation

The cosine basis spans the entire clip, so a single cutoff has to suit both a sustained phrase and a pirouette at once. It cannot. At 6 Hz the phrases are right and the turn dissolves; at 12 Hz the turn sharpens and everything else picks up tracker jitter.

Fitting in segments resolves it — a low cutoff either side, a much higher one across the turn. The hazard is the join: two independently fitted segments choose their coefficients knowing only their own samples, so they disagree at the seam and the splice itself becomes a visible jump. Overlapping the segments and crossfading with a raised cosine spreads the handover across a fifth of a second.
6 Hz
phrases, either side
20 Hz
across the turn
1.93 px
residual in the turn
1.13 px
residual elsewhere
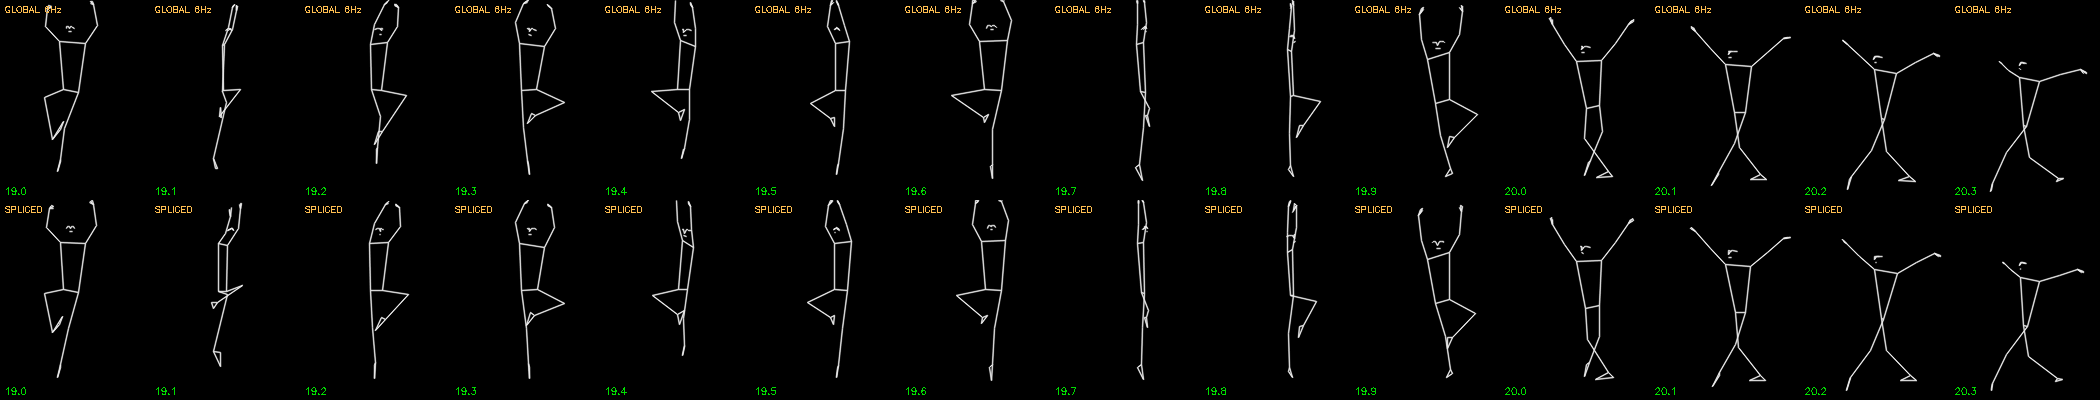
Fourteen frames spanning 19.0 to 20.3 seconds, rendered twice. The upper
                row is a single global 6 Hz fit, in which the limbs smear into a narrow
                vertical shape. The lower row is the spliced fit, in which the working
                leg holds a distinct bent shape and the supporting leg stays a clean line.
The same fourteen frames of the turn, 19.0s to 20.3s. Above: one global 6 Hz fit. Below: the splice. The working leg keeps its shape instead of smearing — the difference is articulation, not position.

Against 6.19 px in the turn for a single global 6 Hz fit, and 2.89 px for a global 12 Hz one that coarsened the rest of the variation to get there. The seams add nothing: measured against the raw data at the same frames, the spliced curve moves less, so it is still smoothing rather than introducing a discontinuity.

What it does not fix. The turn still does not read as a rotation, and no cutoff will make it. A pirouette is rotation about the vertical axis — precisely the axis a camera discards — so in projection it can only ever appear as a narrowing. What the splice recovers is articulation: limbs that hold their shape through the turn instead of smearing.

Method

Costume governs the skeleton; framing governs the matte

Three clips went through identical code, which turned source selection into a controlled experiment. Leg visibility is the pose model's own confidence in the knee and ankle landmarks; span is the fraction of frame height the dancer occupies.

ClipLeg visibilitySpanFrames trackedfps

A romantic tutu drapes over the legs and occludes them; a classical tutu projects horizontally and never crosses them. The classical-tutu clip wins on every axis at once, which is why it is the one analysed here.

Two fixes that missed. The turn was first blamed on left/right limb labels swapping (56 frames, all inside it) and then on the 6 Hz cutoff filtering away real motion. Both were true and neither was the cause. The residual improved and the turn still looked broken, because a single global cutoff was the wrong model — see below.